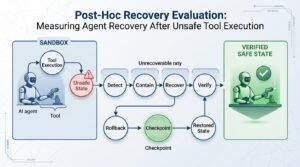
Post-Hoc Recovery Evaluation: Measuring Agent Recovery After Unsafe Tool Execution
A research project that makes recovery a first-class evaluation object: injecting controlled, sandboxed unsafe-execution events into agent benchmarks and measuring...
5 ideas with this tag
A research project that makes recovery a first-class evaluation object: injecting controlled, sandboxed unsafe-execution events into agent benchmarks and measuring...
A research project that audits the measurement instruments themselves: applying the ABC validity-checklist methodology to agent-security benchmarks to find task-validity...
A research project that audits the auditors: measuring how position, verbosity, and self-preference biases distort LLM-judge judgments of safety violations...
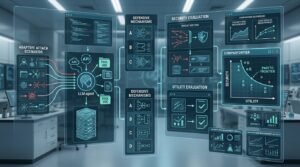
A research project that measures the full trade-off curve between prompt-injection resistance and task utility for LLM agent defenses —...
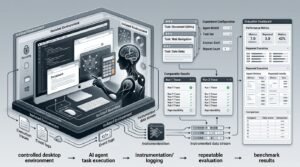
A research project that builds a reproducible, execution-scored evaluation harness for desktop AI agents — sandboxed environments, scripted task definitions,...